Many organisations already have sensors on their remote pump rooms, warehouses and unstaffed utility sites — and still discover problems late. Alarms fire into a group chat that nobody owns. The same event arrives five times. A communications failure leaves the last value on the dashboard looking reassuringly current for three days.
At fleet scale the problem changes shape: electrical, motor, vibration and environmental data sit in separate files, the team spends its time collecting evidence instead of comparing risk, and a noisy but harmless asset steals attention from a quiet critical one.
This guide covers both: making a single remote site produce a dependable response, and prioritising maintenance across many sites.
Part 1: remote sites
The question to answer
Will a meaningful change reach someone who can act on it?
Design the measurement around the decision
Start with the operating decision, then choose the measurement — temperature, humidity, pressure, flow, vibration or a state input. Then:
- validate sensor range, engineering-unit conversion and update rate,
- define normal, out-of-range, missing, stale and disconnected as five separate conditions,
- test the full path, from a controlled sensor change to the responsible person’s phone.
What a useful alert contains
- asset identity,
- time,
- measured value and the limit it crossed,
- how long the condition has persisted,
- data-quality status.
Silence is not health. A device going offline is not proof that the physical process stopped — and the absence of new alarms is not proof that monitoring is working. Monitor the monitoring.
Ownership and escalation
Assign each alarm an owner, an acknowledgement expectation and an escalation route suited to the site. Use the notification channel that is enabled and tested, rather than assuming every messaging service is available. During commissioning, simulate approved alarm and communications-loss scenarios and confirm recovery. Record operational changes in the maintenance workflow, not only in chat.
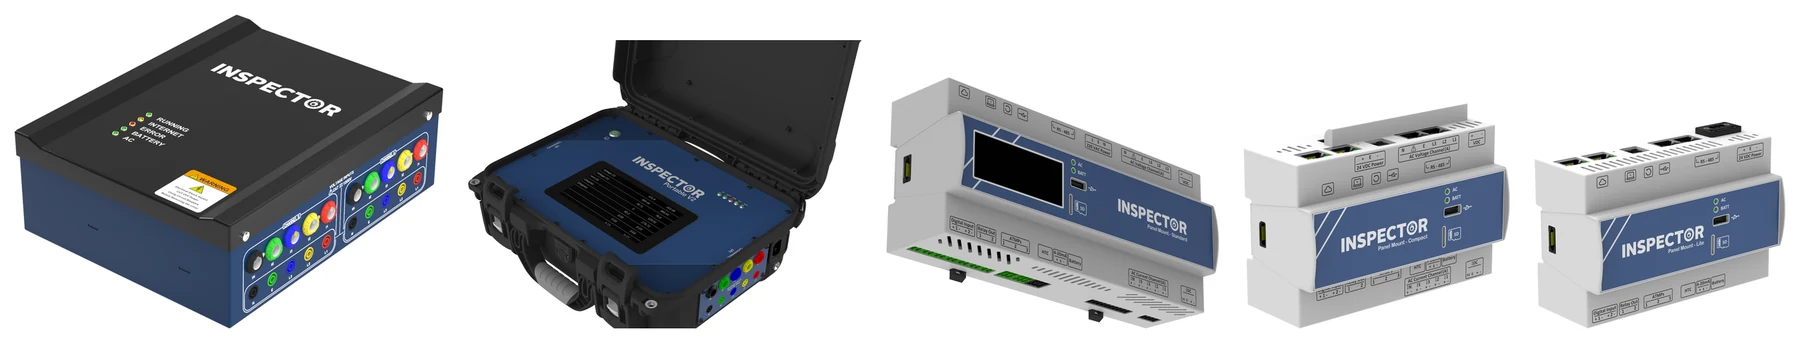
Inspector Panel Mount Lite covers environmental and IoT points economically; an Inspector V4 or Panel Mount Standard adds power quality where electrical events matter. Inspector alerts by SMS, email and app, and stores its data locally on an SD card as well as in the cloud.
General monitoring is not a safety system. Protocol, channel, licence and network support are deployment-specific, and IoT monitoring is not a certified fire, gas, emergency-shutdown or other life-safety system.
Part 2: fleets and multi-site operators
The question to answer
Which asset needs attention first, and what evidence supports that decision?
Build a common structure
- a consistent site and asset hierarchy,
- consistent units and operating-state definitions,
- data-quality indicators on every stream,
- a decision about which raw records and summaries to retain for each use case,
- confirmed time synchronisation, data transfer and permissions for each device family,
- a clear record of which analytics are actually enabled.
Rank risk honestly
Compare each asset with its own baseline before ranking it against dissimilar equipment. Then combine:
- how much the condition has changed,
- how long it has persisted,
- how critical the asset is,
- how confident you are in the data.
A health score should expose its inputs and limitations, not hide them. Trend- and rule-based condition monitoring is useful — but it is different from a validated model that predicts failure or remaining useful life.
Close the loop to maintenance
Create a review queue in which every item has:
- an evidence summary,
- a responsible owner,
- the next inspection,
- a closure criterion.
Transfer evidence into the established maintenance system through a supported integration or a controlled manual process — Inspector Cloud exports PDF for sharing, CSV for analysis and JSON for API integration, and the devices speak Modbus, BACnet, DNP3, IEC 61850, MQTT and SNMP. Feed confirmed findings and post-maintenance measurements back into the asset history. That feedback is what makes the next prioritisation better.
Name only what is validated. Digital-twin, AI, predictive-risk and remaining-life functions must be described only within their validated release scope. A cloud connection alone does not create reliable failure prediction — benchmark any predictive model against defined outcomes before relying on it.
Scale only when the pilot works
Expand to more sites when the pilot produces reliable data, actionable reviews and a verified closure process. More instruments will not repair an unclear operating question or an unowned alarm.
What to measure to show value
- sensor-to-notification delay and acknowledgement time,
- unresolved alarm count and stale-data duration,
- unnecessary dispatches,
- unresolved high-priority conditions,
- evidence-backed work orders and repeat failures,
- time from observation to action.
The target is dependable coverage and a closed response loop — not the largest possible number of notifications.
Related reading
- Predictive maintenance without the hype
- Pharma and cold-chain excursions
- What a power quality analyzer actually tells you
Running many sites with too few engineers?
An engineer will show you how a fleet looks in Inspector Cloud, using your asset list. Book a meeting